Training a network is a high-dimensional, non-convex minimisation
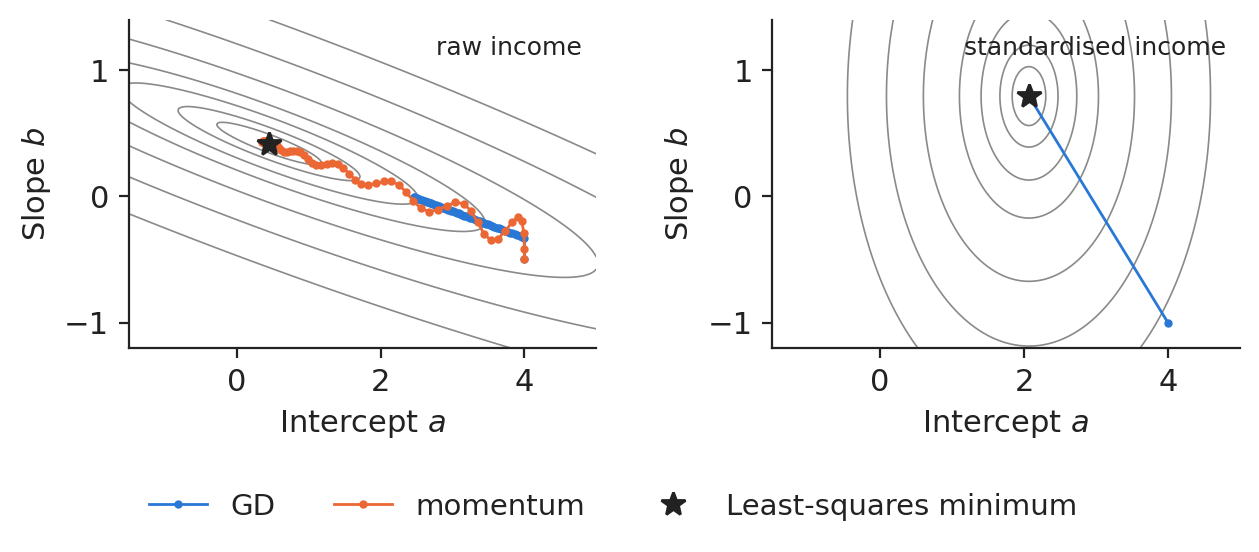
Slide 5 in the PDFThere is no formula for the weights of a network. We start somewhere and repeat \(\boldsymbol\theta_{t+1}=\boldsymbol\theta_t-\eta\nabla\mathcal L(\boldsymbol\theta_t)\): to first order, \(\mathcal L(\boldsymbol\theta-\eta\mathbf g)=\mathcal L(\boldsymbol\theta)-\eta\|\mathbf g\|^2\), so a small step against the gradient lowers the loss. Our MLP 64-64 has 4,801 parameters for 12,384 training block groups.
 NN_L2_gd_paths